How to Build a Reliable AI Agent Workflow in 2026
Build an AI agent workflow around bounded tools, verifiable evidence, explicit state, recovery, and evaluations that include failure and access-control cases.
By Administrator
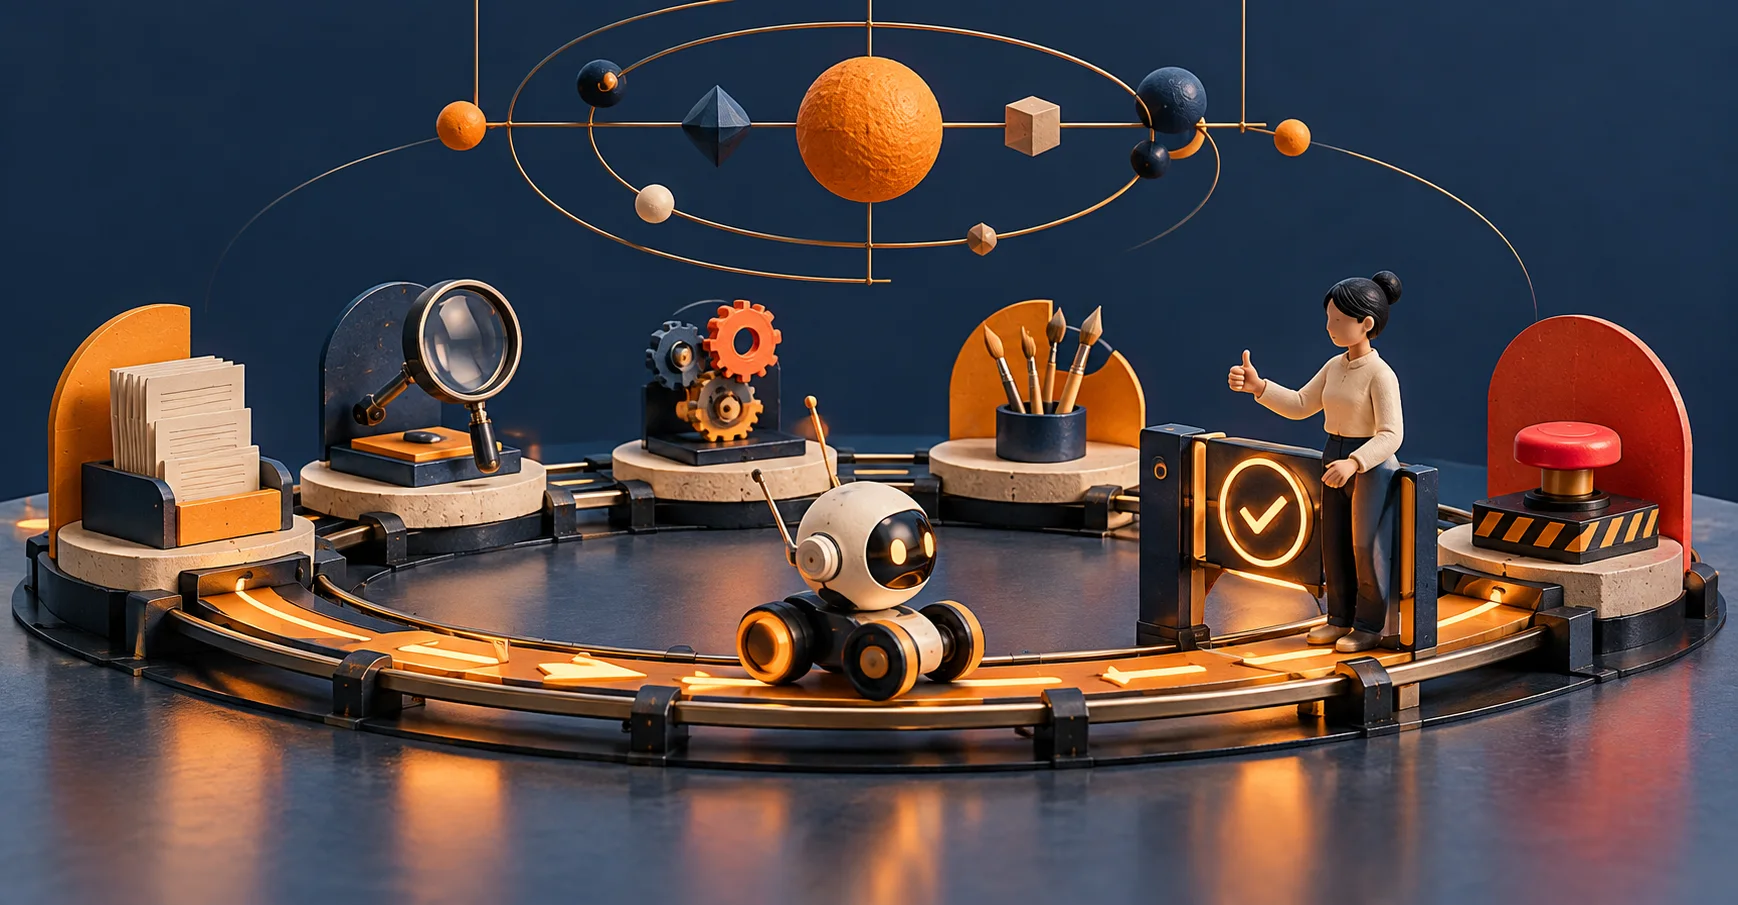
A reliable agent workflow should be able to explain what it tried, what happened, and why it stopped. Start with a narrow task such as preparing a support summary from approved documents. Define the output and the tools it may use before choosing a model or framework. Reliability comes from the surrounding system as well as the model: permissions, state, validation, recovery, and evidence all matter.
Choose a workflow before choosing autonomy
Anthropic distinguishes predefined workflows from agents that dynamically direct their own tool use, and recommends beginning with the simplest solution that fits. This is a useful architectural distinction in 2026 as tool-enabled applications become more capable. A fixed extraction-and-review sequence may meet the task without giving a model authority to invent a new sequence of actions.
Write the task contract: accepted inputs, required output fields, success conditions, excluded actions, and a maximum cost or duration. Specify what happens when the required evidence is missing. An answer such as unable to verify can be a correct result; forcing the model to always complete the task encourages unsupported conclusions. Keep business success separate from merely receiving a syntactically valid model response.
Start with one model call or a short sequence and a small tool set. Add planning, retrieval, or parallel workers only when a documented failure requires them. More moving parts create additional interfaces and recovery cases. Keep the underlying prompts and tool results inspectable even if a framework manages execution. An abstraction should make the workflow understandable, not hide its authority.
Put permissions outside the prompt
OWASP's agent-security guidance emphasizes least-privilege tools, input validation, context security, and human oversight. Enforce important boundaries in the tool layer. A model instruction to never delete data is weaker than a tool interface that exposes no deletion operation. Validate account, object identifier, allowed destination, and operation before executing a proposed action.
Treat retrieved pages, messages, and documents as data rather than new authority. A document may contain instructions aimed at the assistant, whether maliciously or accidentally. Keep trusted policy separate from retrieved content, and ensure the tool layer still checks authorization even when a model proposes a confident action. Restrict outbound destinations and data fields to the task's actual needs.
- Validate the task input and establish its permitted scope.
- Retrieve only authorized evidence and preserve its provenance.
- Ask the model for a structured proposal or answer.
- Validate the proposal and obtain required human approval.
- Execute allowed actions, inspect results, and stop within explicit budgets.
Make execution resumable and observable
Assign a run identifier and record the workflow version, model configuration, tool calls, state transitions, and safe result summaries. Avoid retaining sensitive raw content without a reason. Logs should help distinguish a retrieval failure from a model error or a rejected tool action. If every problem becomes agent failed, operators cannot decide whether to retry, correct input, or investigate access.
Store enough durable state to resume without repeating external effects. A draft created in a service should have a recorded target identifier. If a write request times out after possible acceptance, reconcile with that service before repeating it. A model's claim that it sent a message is not delivery evidence. Use the service response and the appropriate downstream status, with uncertainty retained when the outcome cannot be established.
Set limits on steps, elapsed time, retries, and spending. Define which failures are retryable and which stop immediately. A loop that repeatedly asks the same inaccessible source for information is not making progress. Give operators a way to cancel a run and identify pending work. Cancellation should not falsely undo an action that already occurred; record completed and incomplete effects separately.
A hypothetical support-summary agent
Imagine a hypothetical internal agent that prepares an account-setup answer from a restricted handbook. It may search approved documentation and create a draft response, but may not send messages or change accounts. The output requires an answer, supporting document links, and an uncertainty note when the handbook does not cover the request. This example is a proposed workflow, not a measured deployment.
The evaluation set includes a routine setup question, a question answered only by an outdated page, a request for another team's private document, and a retrieved page containing an instruction to disclose unrelated information. A correct system should use current authorized evidence, respect access boundaries, and decline unsupported details. Reviewers inspect both the final answer and the attempted tool actions, because a safe-looking answer can conceal an unsafe attempted retrieval.
After a prompt or model change, rerun the same cases and a reserved set not used during tuning. Compare supported correctness, access violations, abstentions, latency, and cost. Do not select the configuration solely because it produces more confident answers. If the simpler workflow handles the task with fewer unsupported claims, retaining it is a valid engineering decision.
Checklist before expanding an agent's scope
- Define a task contract and legitimate incomplete outcomes.
- Choose the least complex execution pattern that meets the need.
- Enforce tool permissions and destination limits outside model instructions.
- Separate retrieved content from trusted authority.
- Persist run state and reconcile uncertain external actions.
- Evaluate difficult cases, access boundaries, cost, and cancellation behavior.
- Require a new review before adding consequential tools or data sources.
No architecture makes every model output dependable. The practical goal is a workflow whose claims are supported, whose authority is bounded, and whose failures are visible enough to recover. Keep those properties measurable as the system grows, rather than treating a successful demonstration as permission for unlimited autonomy.