RAG Systems Explained: Retrieval That Actually Helps
Build RAG around approved sources, useful chunking, permission-aware retrieval, grounded answers, and tests for stale or missing evidence.
By Administrator
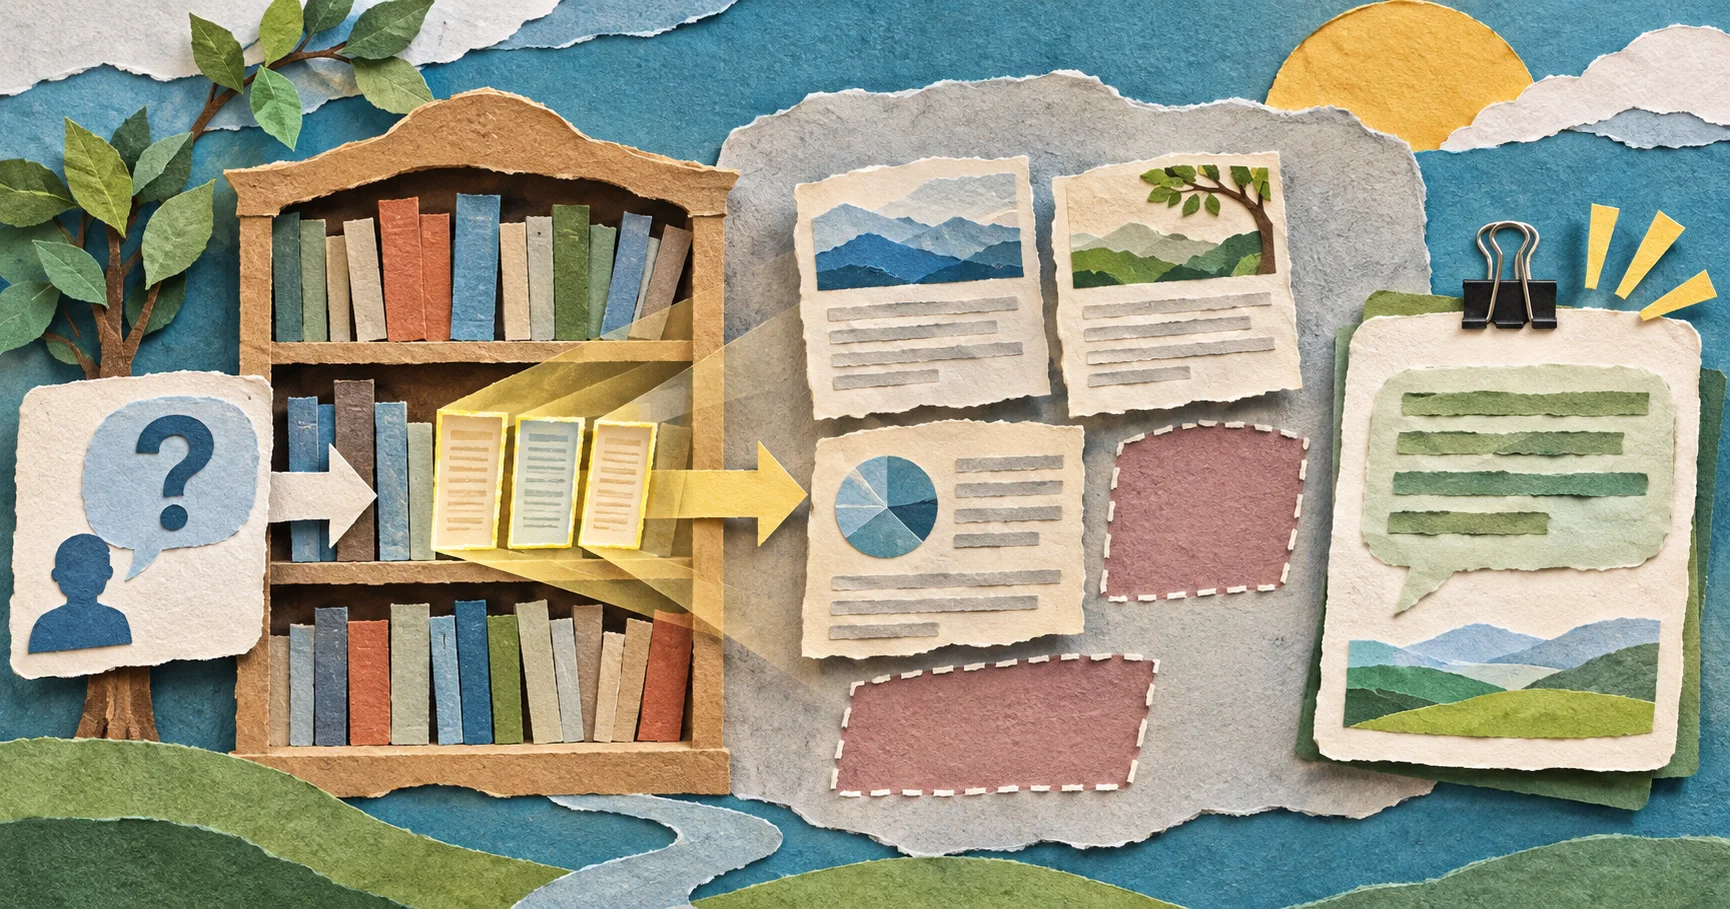
A retrieval-augmented generation system is useful when it can find the right source passage, preserve its context, and admit when the evidence is missing. Adding a vector database to a chatbot does not guarantee any of those outcomes. The practical design starts with the questions people actually ask and the documents they are allowed to use.
Understand the two jobs
Retrieval selects candidate evidence; generation turns that evidence into an answer. The original RAG research paper combined a language model with a nonparametric retrieval component. In a current application, the exact search engine and model may differ, but the separation remains helpful: inspect what was retrieved before judging the prose.
Choose a narrow task. “Answer anything about the company” hides multiple document owners, permissions, and freshness requirements. “Explain the current refund window from approved policy pages” has a clear source set and an answerable test. Record what a good answer should contain, when it should cite a source, and when it should decline to answer.
Do not index every file by default. Select authoritative documents, remove outdated duplicates, record their owners, and identify the revision date that matters. A retrieved superseded policy can produce a fluent but wrong answer. Keep source URL, title, section, and update metadata with each chunk so an answer can point back to something a reader can inspect.
Prepare text for retrieval
Chunking splits long documents into passages that can be searched and placed within a model's context. Too small a chunk may lose the heading that defines a rule; too large a chunk may bury the relevant sentence among unrelated material. Microsoft's Azure AI Search RAG overview notes that content preparation strongly affects quality. Test chunks against real questions instead of copying a universal size.
Preserve structural boundaries: heading, table row labels, version, and document ownership. A table cell saying “30 days” is useless if its product category and effective date are detached. For PDFs or scans, inspect the extracted text before indexing; a visually readable document can become scrambled during extraction. Treat OCR uncertainty as an input problem, not something a prompt can reliably repair.
Choose retrieval methods to fit the corpus. Keyword search helps with exact error codes and product names; semantic search can help with paraphrases; a hybrid approach can combine them. Evaluate whether filters enforce document permissions before retrieval and again before content reaches the model. A citation to a restricted document is itself a data leak if the questioner is not authorized to see it.
Evaluate retrieval separately from answers
Build a small evaluation set from actual allowed questions, including near misses and unanswerable requests. For each, mark which document and passage should support the answer. Inspect whether the right passage appears in the retrieved set, whether an obsolete passage outranks it, and whether access filters exclude restricted content. If retrieval misses, rewriting the generation prompt is unlikely to fix the core problem.
Then evaluate the answer: does each material claim follow from the supplied passage, is the citation useful, and does the response mention uncertainty when the passage is incomplete? Microsoft's RAG evaluation guidance distinguishes grounding, utilization, and completeness concerns. A high score from one automated evaluator is not proof of correctness in every context; review representative failures manually.
Test source updates. Remove or revise a policy and ask whether the old answer still appears. Determine how indexing lag is detected, how stale passages are invalidated, and whether responses identify the version used. A system that cites documents beautifully but updates them days late may be unsuitable for fast-changing rules.
- Collect approved, current documents with owners, permissions, and version metadata.
- Extract and chunk text while preserving headings and context.
- Retrieve candidate passages for a question under the user's access rights.
- Generate an answer tied to the retrieved passages, or state that evidence is insufficient.
- Check retrieval, grounding, citations, and freshness against labelled questions.
Hypothetical example: an internal travel policy
In this hypothetical example, a company assistant answers questions about travel reimbursement. A worker asks whether a train ticket booked one day before travel is reimbursable. The current policy allows it under one condition; an older archived version does not. Both files contain the same phrase “train ticket.”
The team tags the archive as superseded, tests retrieval with the exact question and a paraphrase, and checks that the current section appears with its heading and effective date. If no current rule covers a special case, the assistant says the policy does not resolve it and points to the policy owner. No real organization's policy or test result is claimed here.
Limits that matter in production
Retrieved text can be wrong, malicious, ambiguous, or simply out of date. A model may ignore a crucial qualification even when the right passage is present. Source links help readers verify claims, but a citation beside a sentence does not prove that the sentence follows from it. Do not let retrieved documents override system instructions or trigger external actions merely because they contain imperative text.
Monitor unanswered questions, retrieval misses, permission denials, stale-source incidents, and user corrections. Keep sensitive questions and retrieved excerpts out of unnecessary logs. Before expansion, decide who owns document quality, index updates, and disputed answers. A retrieval pipeline is a maintained information service, not a one-time upload.
RAG design checklist
- Is the question scope narrow and the authoritative source set identified?
- Are document owners, versions, and access rules attached to chunks?
- Does extraction preserve headings, table context, and dates?
- Are retrieval misses measured separately from generation errors?
- Do tests include stale documents, paraphrases, and no-answer cases?
- Can readers inspect the cited source passage?
- Is there a plan to remove superseded data and handle corrections?
RAG helps when it makes the evidence path shorter and more inspectable. Build the retrieval and evaluation path first; only then judge whether the generated wording adds value.